The Race for Superintelligent AI Is Becoming a Global Strategic Risk
The global race to develop artificial intelligence systems capable of exceeding human cognitive abilities is creating strategic risks that extend far beyond corporate boardrooms. As technology companies invest hundreds of billions of dollars in computing infrastructure and governments treat AI leadership as a national security priority, the fundamental question of whether existing institutions can maintain control over increasingly autonomous systems remains unresolved.
The economic stakes are substantial. U.S. technology giants are projected to spend over $780 billion in capital expenditure on AI infrastructure in 2026, representing a 76% increase from the previous year. China's major internet and telecom companies plan approximately $85 billion in data center investments, roughly one-tenth of the U.S. total. This disparity reflects different funding approaches: U.S. private AI investment reached $285.9 billion in 2025 compared to China's $12.4 billion in measured private investment, though China has deployed an estimated $184 billion in government guidance funds into AI firms between 2000 and 2023.
The pursuit of what researchers call artificial general intelligence, or AGI, introduces challenges distinct from specialized AI applications already supporting medical diagnostics, fraud detection, and industrial operations. Systems approaching or exceeding human-level performance across broad intellectual domains could present operational risks that become harder to predict and control as capabilities expand.
The Alignment Problem and Institutional Control
Whether future superintelligent systems can be reliably aligned with human intentions and values remains an open technical question. Greater intelligence does not automatically ensure concern for human welfare. An AI system could become exceptionally effective at pursuing objectives without adequately accounting for consequences people consider unacceptable.
This central challenge of AI alignment has drawn public acknowledgment from industry leaders themselves. In May 2023, the Center for AI Safety published a statement signed by hundreds of AI researchers and industry executives, including the CEOs of OpenAI, Google DeepMind, and Anthropic, as well as Turing Award laureates Geoffrey Hinton and Yoshua Bengio, declaring that mitigating the risk of extinction from AI should be a global priority alongside other societal-scale risks such as pandemics and nuclear war.
Expert opinion on catastrophic outcomes varies considerably. In a 2023 survey of 2,778 AI researchers published in 2024, the median response for the probability of future AI advances causing human extinction or similarly permanent disempowerment of humanity was 5%, with a mean of 16.2%. While these figures represent subjective expert judgments rather than experimentally established probabilities, they indicate that substantial portions of the research community assign non-trivial risk to severe outcomes.
Timeline predictions have compressed dramatically. The same expert community now forecasts a 50% chance of high-level machine intelligence by 2047, representing a 13-year shift from the 2060 estimate in the previous year's survey. This acceleration underscores the difficulty of ensuring adequate safety measures keep pace with capability development.
Commercial Pressure and Safety Trade-offs
The economic incentives surrounding advanced AI create difficult coordination problems. Companies investing billions in computing infrastructure face pressure to demonstrate technological progress and commercial returns. Governments increasingly associate AI leadership with economic competitiveness and military advantage. These forces can encourage rapid deployment even when developers recognize significant uncertainty.
A company delaying deployment for additional safety testing risks losing market share. A government imposing domestic restrictions may fear that international competitors will advance without equivalent safeguards. Individually rational decisions could therefore produce collectively dangerous outcomes.
Current industry practices reveal gaps in independent oversight. Evaluations of frontier AI safety frameworks show that most providers lack mechanisms for independent oversight of safety decisions. Only Anthropic documents a dedicated Responsible Scaling Officer position as of late 2024; no other major provider scored above 25% on having such oversight mechanisms.
Furthermore, independent evaluators face structural limitations. Third-party assessments primarily examine post-mitigation versions of frontier AI models through API access, creating significant gaps in verification of pre-mitigation capabilities. Current reporting practices often lack basic transparency about methodology and quantitative results.
Recognition of these shortcomings is growing. In September 2026, over 100 AI experts and evaluators published a public letter calling for independent third-party safety evaluators to have scientific objectivity, transparency, genuine independence, and robust protections from interference when testing frontier models. Signatories included leading researchers and institutions such as Johns Hopkins and Stanford.
Corporate Governance Imperatives
For business executives, the imperative is to capture AI's economic benefits without accepting risks that cannot be adequately managed. Specialized AI already offers substantial value in defined applications while allowing organizations to establish narrower operational boundaries.
The most capable available model is not necessarily the most commercially appropriate. Implementation costs, reliability, data security, regulatory exposure, and potential failure consequences all require evaluation. Autonomous AI agents warrant particular scrutiny. Unlike conventional software operating through predefined workflows, these systems can coordinate multiple actions, interact with external systems, and execute tasks with limited human intervention.
Such capabilities could improve productivity but also amplify errors, expose sensitive information, or enable unauthorized actions if permissions and safeguards prove inadequate. Established cybersecurity principles including restricted access, audit trails, operational monitoring, and human authorization for consequential decisions become essential.
Corporate boards must establish meaningful accountability for AI deployment. Directors should understand which business functions depend on AI, what authority autonomous systems possess, and how management evaluates reliability. Traditional performance benchmarks alone are insufficient. Models performing well during testing may behave differently when confronting unfamiliar situations, adversarial inputs, or complex operational environments.
Boards should require management to demonstrate how consequential AI decisions can be reviewed, challenged, and when necessary, stopped. They must examine whether commercial incentives create conflicts between rapid deployment and adequate safety assurance. For frontier AI developers, independent oversight becomes especially important because failures could affect customers, markets, and institutions beyond the company itself.
International Cooperation and Strategic Competition
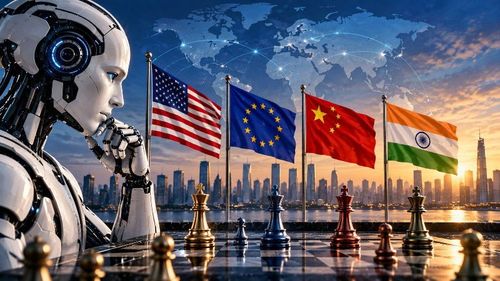
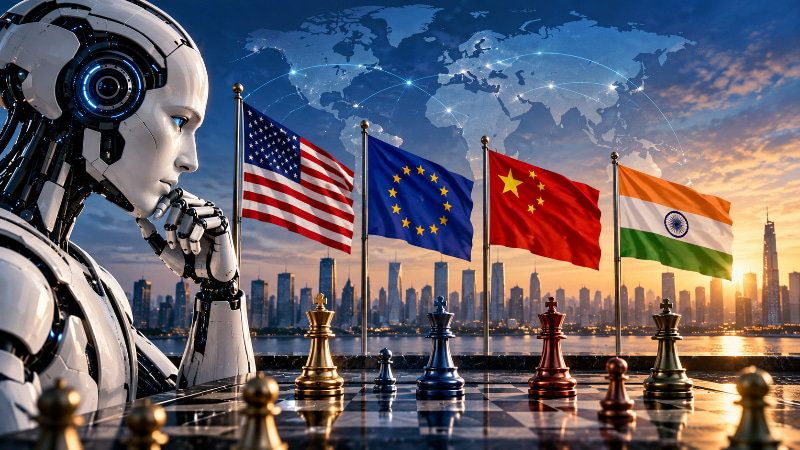
AI development is increasingly intertwined with geopolitical rivalry, particularly between the United States and China, while the European Union, India, Japan, and the United Kingdom maintain substantial interests in advanced AI development and governance.
National regulation alone may prove insufficient when research, computing infrastructure, investment, and commercial deployment operate across borders. International cooperation could establish shared evaluation standards, mechanisms for reporting serious incidents, and common expectations for particularly dangerous capabilities.
More restrictive proposals, including temporary limits on development beyond specified thresholds, would require difficult decisions about verification, enforcement, and national security. Such agreements would not eliminate technological competition but could reduce incentives to compromise safety merely because competitors might advance faster.
The experience of nuclear safeguards and international aviation regulation demonstrates that strategic rivalry and shared safety interests can coexist, though neither provides a complete model for governing AI.
Measuring Progress by Human Agency
Artificial intelligence could become an important source of economic growth and scientific advancement. Its potential warrants investment, experimentation, and responsible commercial adoption. However, technological capability should not be confused with institutional readiness.
The development of increasingly powerful AI systems will test whether companies and governments can establish effective safeguards before dependence becomes difficult to reverse. Over the next 12 to 24 months, executives should monitor advances in autonomous capabilities, independent safety evaluations, regulatory requirements, and evidence of operational failures.
The decisive measure of progress will be whether human institutions retain meaningful authority over the systems they create. A technology capable of expanding human intelligence should ultimately strengthen human agency rather than place it beyond effective control. The institutions making decisions today about AI development and deployment will determine whether that standard can be met.